
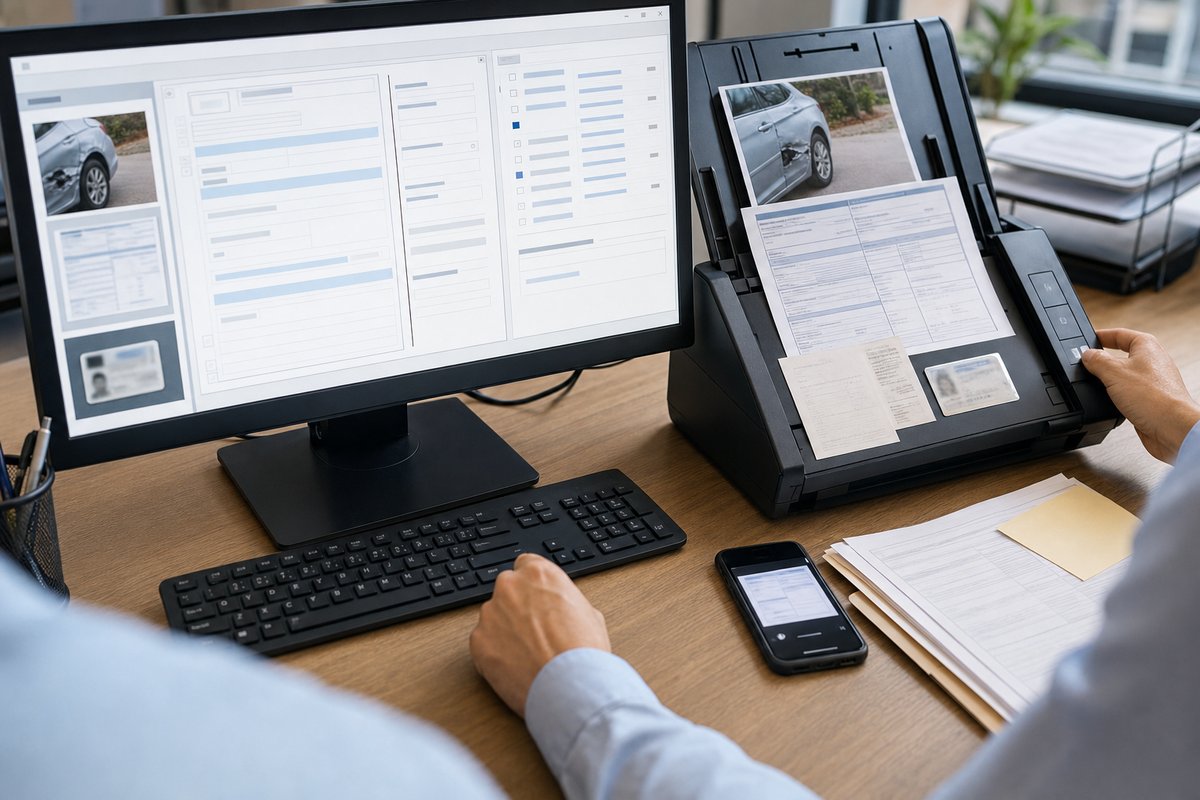
Why claims intake is still where insurance operations get stuck
If you work in insurance operations, you already know the problem isn’t just volume. It’s variation—not just volume. One claim comes in as a clean PDF from an agent. The next shows up as a phone photo of a repair estimate, along with a handwritten form, an email thread, and a police report attachment with sideways pages.
And somehow your team still has to turn that mess into a usable claim record fast, accurately, and in a way that stands up to audit review.
That’s where document intelligence comes in. When people ask How to Automate Insurance Claims Intake with Document Intelligence, they’re usually asking a more practical question: how do you stop paying skilled staff to retype basic claim data from incoming documents without creating an even uglier exception queue on the back end?
The good news: in a lot of environments, this is very doable—especially if you’re already working inside the Microsoft stack with Azure, Power Automate, SharePoint, Dynamics 365, or a claims platform that connects through APIs. But it only works when the design follows the real intake process, not a polished product demo.
What document intelligence really does in a claims intake workflow
At a practical level, document intelligence takes incoming files and figures out what they are, what data matters, and where that data should go next. That might mean recognizing an ACORD form, pulling the policy number, extracting claimant details, identifying dates of loss, reading line items from an auto repair estimate, or flagging a missing signature.
That’s a big step beyond simple OCR. OCR can give you searchable text. It does not tell you what matters in that text or what to do with it next. If you’ve ever tested scanning software and thought, “Okay, great, now I can search the document—but a person still has to make sense of it,” you’ve already seen why OCR is not enough.
The value shows up when text recognition is paired with classification, field extraction, validation rules, confidence scoring, and workflow routing. If you want the non-technical version of that stack, this explanation of how document intelligence works lays it out in plain English.
For insurance claims, you’re not just digitizing paper. You’re building a front door that can sort, read, and triage claim documents before an adjuster or intake specialist ever touches them.
What a typical automated claims intake process looks like
Most insurance organizations don’t have one clean intake source. Claims show up through email, agent portals, web forms, mobile uploads, fax-to-email systems, contact center attachments, or scanned mail. So the first move is treating intake like a system, not just a mailbox somebody keeps checking.
A solid automated flow usually looks something like this:
- Capture documents from email, portal uploads, scanners, or shared folders
- Classify each file by document type, such as FNOL form, police report, repair estimate, medical bill, proof of identity, or correspondence
- Extract key fields based on the document type
- Validate the data against business rules and policy or claim systems
- Route low-risk, high-confidence items automatically
- Send exceptions to a human review queue with the problem clearly identified
- Write approved data into the claims system, CRM, or case management platform
- Store the original file and extracted data with an audit trail
That’s the basic shape of a document intelligence pipeline. And yes, the technology matters. So does the handoff logic. The best setups don’t try to automate every strange edge case. They handle the predictable middle well and make the weird stuff faster for your team to untangle.
Which claim documents are the best place to start
If you’re evaluating this for the first time, don’t lead with the hardest documents in the building. Start with the ones that are high-volume, repetitive, and annoying enough that your team will feel the difference almost immediately.
In many insurance environments, a few categories usually rise to the top:
- First notice of loss forms
- ACORD forms
- Driver’s licenses and identity documents
- Repair estimates from shops like Caliber, Gerber, or dealership service centers
- Medical invoices and explanation of benefits documents
- Police reports
- Proof of insurance or declarations pages
- Claim-related correspondence and email attachments
In my view, the best pilot is usually one document family with a clear business destination. Auto claims teams often get quick wins by automating repair estimates and FNOL forms first. Workers’ comp teams may get more value from medical bill and incident-form extraction. Property claims teams often start with contractor estimates and proof-of-loss documents.
The key is choosing a workflow where the extracted data actually kicks off an action. If all you do is dump fields into a spreadsheet, intake is still broken—you just made it digital.
What data should be extracted from insurance claim documents
This depends on the line of business, but most claims intake teams are after a pretty familiar set of fields. You need enough information to open, route, validate, and prioritize the claim without asking staff to key in what the document already says.
Common fields include:
- Policy number
- Claim number, if one already exists
- Insured and claimant names
- Date of loss
- Loss location
- Type of loss
- Vehicle, property, or incident details
- Contact information
- Provider, shop, or vendor name
- Invoice or estimate amounts
- Document dates
- Signatures, initials, or missing attachments
But this is where a lot of teams trip up: not every field deserves the same confidence threshold. A shop phone number is nice to have. The policy number and date of loss are not optional. Your workflow should treat those fields very differently.
That sounds simple, but it changes the whole design. It means you can auto-process a document when the critical fields are strong, while still flagging non-critical gaps for later cleanup. That’s often the difference between a system people trust and one they keep overriding because it feels risky.
How Microsoft tools fit into the solution
If your organization already uses Microsoft 365, Azure, and Power Platform, you’ve got a practical foundation for this kind of automation. You don’t need to jam everything into one product, but the pieces fit together well when each one has a clear job.
A common setup might look like this:
- Azure AI Document Intelligence to classify and extract data from claim documents
- Power Automate to move files, trigger workflows, route exceptions, and update downstream systems
- SharePoint or Azure Blob Storage to store source documents and supporting files
- Dataverse or Dynamics 365 to manage case data, queues, and review tasks
- Microsoft Teams for operational notifications and exception handling
- Power Apps for lightweight review screens when staff need to correct extracted data
In real projects, organizations usually connect this stack to the core claims platform rather than replacing it. That matters. Claims leaders generally do not want another disconnected tool sitting off to the side. They want intake data to land where adjusters already do their work.
And if your team is still getting oriented on the broader document extraction process, it helps to think of claims intake as one business-specific version of that bigger pattern.
What automation should handle, and what should still go to a person
One of the most common mistakes in claims automation is treating “automated” as if it means “no human review.” Mature insurance operations don’t work that way—and honestly, they shouldn’t.
You still want people involved when a document is unreadable, extracted values conflict with your policy system, the claimant name doesn’t match, the date of loss is ambiguous, or a form is missing a required page. The point isn’t to remove judgment. It’s to stop burning judgment on routine data entry.
A good rule of thumb is to automate when all three of these are true:
- The document type is recognized with high confidence
- Required fields are extracted clearly
- The data passes basic validation against your system rules
Route it to review when any one of those fails.
That review queue should be clean and focused, not a dumping ground. The reviewer should see the original document, the extracted values, the confidence issue, and the next action needed. If they have to reconstruct the story across five systems, you didn’t remove the pain—you just moved it.
Why validation matters as much as extraction
Extraction gets most of the attention because it’s the flashy part. Validation is where insurance teams decide whether the system is trustworthy or not.
Say a repair estimate shows claim number 874521, but your system has 874251. Or the claimant’s last name on the police report doesn’t match the FNOL form. Or the uploaded medical invoice predates the policy effective date. Those aren’t extraction failures. They’re business exceptions.
This is also where automation can improve quality, not just speed. Instead of hoping every intake specialist catches every mismatch by hand on a busy day, you can run the same checks every single time.
That also helps reduce compliance risk. Not because software is magically compliant on its own, but because it creates consistency, traceability, and a record of what was extracted, validated, corrected, and approved.
The trade-offs you should expect before you start
Document intelligence is powerful, but it’s not magic. Better to go in with your eyes open.
Document quality matters. If you’re working with blurry phone photos, handwritten notes, low-resolution scans, or forms that have been printed and rescanned three times, results will bounce around. A lot of teams find that clearer intake instructions for agents, customers, or field staff can raise automation rates almost as much as model tuning does.
Document variation is real too. A police report from one jurisdiction may look nothing like one from another. Medical bills come in all kinds of formats. Repair estimates vary by vendor system. Your design needs room for multiple templates, fallback logic, and a review path when the model runs into something unfamiliar.
And the long tail never really disappears. There will always be oddball documents. The smart play is not chasing 100 percent automation. It’s deciding what meaningful share of intake volume should move faster with less manual effort, then making the rest less painful to manage.
That last point gets overlooked all the time. You do not need perfect AI to get a very solid operations result.
How to run a pilot that tells you something useful
If you want a pilot that leads somewhere real, keep it narrow enough to measure and broad enough to matter. Pick one claim type, one document family, one intake channel, and one destination system.
For example, you might automate emailed auto repair estimates for personal auto claims and push extracted totals, vendor name, and claim number into your claims platform. Or you might process uploaded FNOL forms and create a pre-populated intake record for a human to review.
Then define success in business terms, not just AI terms. Useful pilot questions include:
- How much manual rekeying did you remove?
- How much faster did intake records become available to adjusters?
- How often did staff need to correct extracted values?
- Which exception types came up most often?
- Did the workflow reduce backlog during busy periods?
- Did supervisors trust the audit trail and review process?
Those answers will tell you more than a model accuracy screenshot ever will.
One overlooked benefit: better work distribution for your claims team
Here’s something that doesn’t get enough attention. Automating claims intake isn’t just about speed. It can change how work gets distributed across the team.
When intake staff spend less time reading basic fields off forms and attachments, they can focus on exceptions that actually need judgment. It can make onboarding easier too, since newer team members can start with structured review tasks instead of trying to memorize every document type right away.
For managers, that creates more staffing flexibility. During weather events, seasonal surges, or large loss periods, you’re less dependent on a small number of experienced people who know how to decipher every incoming file manually.
And that kind of operational resilience is often every bit as valuable as the raw time savings.
What to do next if you’re evaluating this now
If you’re seriously looking at how to automate insurance claims intake with document intelligence, don’t start by shopping for features. Pull 50 to 100 real intake documents from one claims workflow and review them with operations and IT together.
Group the documents by type. Mark which fields actually matter. Identify what has to be validated. And pay attention to where time gets lost today: opening claims, indexing attachments, rekeying estimates, checking for missing forms, or routing work to the right queue.
From there, map a small but complete workflow. One intake source. One document set. One review path. One system destination.
That gives you something you can test in the real world—with real documents, real exceptions, and a clear path to scale if it works. That’s usually the moment claims automation stops being a slide deck idea and starts becoming a tool the team will actually use.


