
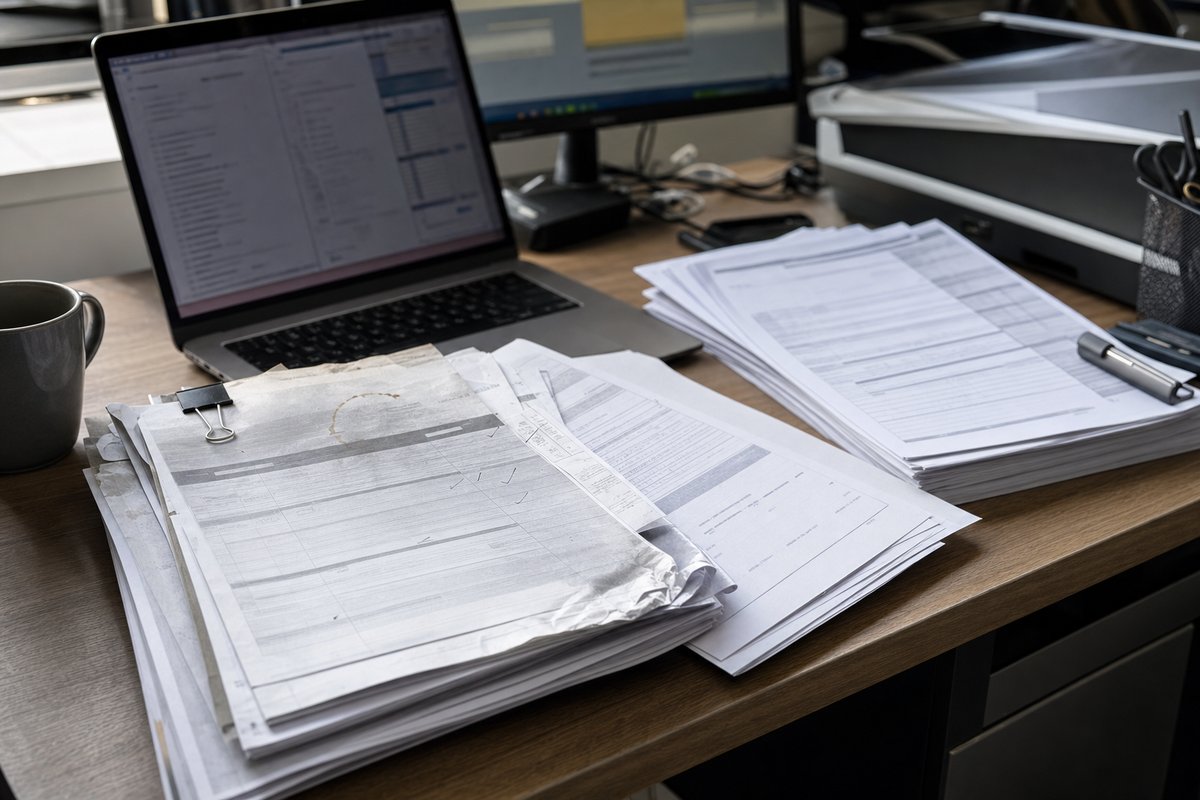
What changes between the demo and the real world
Your document model looked great in testing. Then it hit production, chewed through a week of real invoices, forms, or delivery receipts, and things got messy fast. Fields disappeared. Vendor names ended up in the wrong place. Dates looked fine on one file and totally wrong on the next.
That’s common. And no, it doesn’t automatically mean the model is bad.
Most of the time, accuracy drops because production is where documents stop acting nice. In a pilot, you’re usually working with cleaner files, fewer exceptions, and a tighter range of formats. In production, you get scans from old copiers, phone photos from field staff, PDFs generated by five different ERP systems, and forms somebody quietly changed three months ago.
If you want a quick primer on how document intelligence works, it helps to remember this: the model isn’t “reading” like a person. It’s picking up patterns in layout, text, labels, and structure. When those patterns shift, accuracy tends to slide right along with them.
The good news is that production accuracy problems are usually fixable. But you do have to identify the actual problem first. Most teams, at least from what I’ve seen, don’t really have a model problem. They have an input, process, and governance problem.
Reason #1: Your training set was too clean
This is probably the biggest one. Teams often train on the best documents they can find because those are the easiest to label. Nice digital PDFs. Straight scans. Standard templates. Everything readable. Everything centered.
Then production rolls in with the ugly stuff.
Think about a typical accounts payable process. During a proof of concept, you might train on ten invoice samples from vendors like Microsoft, Staples, and a regional supplier that all send digital PDFs. In production, somebody uploads a wrinkled invoice from a local contractor, a screenshot from an email attachment, and a scanned copy with a coffee stain across the total due.
The model didn’t suddenly get worse. Your sample set just wasn’t a match for reality.
When you build a custom document model, the training set has to include the mess your business actually gets. Not just the ideal version of it. That means:
- low-resolution scans
- skewed pages
- multi-page files
- forms with handwriting in some fields
- documents with stamps, highlights, or signatures over text
- older templates still floating around in the business
And here’s the part a lot of teams miss: you also need negative examples. Files that look similar but should not be processed the same way. A quote is not an invoice. A purchase order acknowledgment is not a packing slip. If your model or classifier hasn’t seen those near-miss documents, it can make the wrong call with a lot of confidence—which is its own kind of headache.
Reason #2: Document formats drift over time
Production environments change quietly. Vendors redesign invoice templates. Internal forms get updated by a business unit. A merger brings in a second set of document standards. Nobody tells the automation team because, from their point of view, “it’s still the same form.”
But to the model, it’s not the same form at all.
Even small layout changes can matter. Maybe the invoice number moves from the top right to the bottom left. Maybe the “Bill To” block turns into a table. Maybe the date label changes from “Invoice Date” to “Document Date.” A person adjusts in a second. A model trained on the old structure may not.
This is why document automation isn’t a one-and-done deployment. It needs maintenance, same as any other business system. The teams that hold up well in production usually have a simple review cycle: look at failed extractions, identify new formats, add representative samples, retrain when needed, and test before rolling updates live.
If that sounds more operational than technical, that’s because it is. A lot of pilot to production challenges come down to change management more than AI itself.
Reason #3: Classification is weak, so the wrong model gets the document
Sometimes the extraction model takes the blame for errors that started a step earlier. The wrong document got routed to it.
Let’s say you have separate models for invoices, W-9s, onboarding forms, and proof-of-delivery documents. If a proof-of-delivery scan gets classified as an invoice, the invoice model will still try to extract invoice fields. You’ll get garbage output, but the real issue was classification.
This matters a lot in mixed mailboxes and shared upload channels, where people send whatever they’ve got. A vendor might attach an invoice and a statement in the same email. A branch office might scan a packet with multiple document types into one PDF. If your intake process assumes every file is one clean document of one type, production will humble that assumption pretty quickly.
In practice, you want to validate the full document intelligence pipeline, not just the extraction model by itself. That includes ingestion, splitting, classification, extraction, confidence scoring, exception handling, and downstream posting into systems like Dynamics 365, SharePoint, or Dataverse.
One thing people don’t always account for: better extraction won’t rescue a bad routing design. If the wrong files keep landing in the wrong branch of the workflow, retraining the model may barely move the needle.
Reason #4: OCR quality falls apart on bad images
Before a model can extract fields, the text usually has to be recognized correctly. So OCR quality matters more than many teams expect.
If your production input includes scanned TIFFs, photos taken in a warehouse, faxed forms, or PDFs built from embedded images, you’re not only testing field extraction. You’re also testing whether the underlying text is readable enough for the service to interpret.
Common problems include:
- blurry camera images
- cropped edges
- rotated or upside-down pages
- dark backgrounds or shadows
- compressed scans that smear characters together
- tiny fonts from legacy systems
And OCR errors can be sneaky. “8” becomes “B.” “0” becomes “O.” A decimal point disappears. That’s all it takes to break a total amount, PO number, or account code.
So don’t just review the extracted field values. Review the recognized text layer too. In Azure AI Document Intelligence or AI Builder scenarios, that often tells you whether the issue is model mapping or plain old readability.
If your users are uploading files through Power Apps, email, Teams, or SharePoint, set expectations for acceptable file quality. Better yet, put a few light guardrails into the process. Reject unreadable images. Flag low-confidence scans. Ask for resubmission before bad data gets into ERP or finance systems.
Reason #5: Production documents have more exceptions than you planned for
Pilots are tidy. Real business processes are not.
An invoice might have no purchase order because it’s for utilities. A claim form might be missing page three. A contract packet might include supporting documents in a random order. A receiving document might have handwritten notes that matter to the workflow but weren’t part of the original extraction plan.
These aren’t edge cases in the annoying sense. They’re often normal business cases that just never made it into the first model design.
That’s why exception handling deserves as much design attention as extraction. When confidence is low, what happens next? Does the file go to a queue in Power Apps? Does a reviewer see the source image alongside extracted values? Can they correct and resubmit without leaving the workflow? Does the corrected data get captured for future retraining?
If you’ve built an AI Builder document flow, this is where the surrounding process matters just as much as the AI step itself. A decent model with a strong review loop often does more for the business than a slightly better model with no exception path.
Reason #6: You’re judging accuracy in a way that hides the real issue
“Accuracy” sounds straightforward, but teams often mean different things when they use the word.
Are you measuring whether the model found the field at all? Whether the value was exactly correct? Whether the value was usable downstream? Whether the document was processed without human touch? Those are very different measures.
For example, if a model extracts “09/01/26” instead of “9/1/2026,” that may count as a mismatch in strict testing, but it might be perfectly usable once normalized in Power Automate or a validation step. On the other hand, if the invoice total is off by one digit, that’s a business-critical failure even if every other field is perfect.
So break performance into categories:
- classification accuracy
- field-level extraction accuracy
- confidence score reliability
- straight-through processing rate
- human review rate
- business acceptance rate in downstream systems
That gives you a much clearer picture of what’s actually failing in production. Sometimes the model is doing a decent job, but downstream validation rules reject outputs because supplier names don’t match master data exactly. That fix is different from retraining extraction.
Reason #7: Your business rules are doing more damage than the model
This one catches a lot of teams off guard.
You may have a solid extraction result, but then a brittle rule breaks the process. Maybe a vendor ID has to match an exact format. Maybe a date has to land in U.S. format even though one division receives documents from Canada or Europe. Maybe the workflow rejects invoices without a PO even though a whole category of approved spend never has one.
From the user’s perspective, “the AI got it wrong.” But sometimes the AI got it mostly right and the workflow just didn’t know what to do with normal variation.
In Microsoft environments, we often see this when Power Automate flows, Dataverse tables, SharePoint columns, and ERP business rules are designed separately. Each piece makes sense on its own. Together, they create failure points that look like model inaccuracy.
That’s why I’d review sample failures end to end. Start with the original document. Check OCR output. Check extraction. Check confidence. Check mapping. Check validation. Check the final write-back step. A lot of the time, the model is only one part of the story.
What to do when accuracy drops
Once you know why performance is slipping, the fix is usually practical—not magical.
1. Build a failure review loop
Pick a sample of failed or low-confidence documents every week. Review them with both the business team and whoever owns the automation. Tag the reason: bad scan, wrong document type, new layout, missing page, OCR issue, mapping issue, or business rule issue.
That one habit can change everything because it stops the vague “the model isn’t working” conversation and turns it into categories you can actually fix.
2. Retrain with real production samples
Use documents from live operations, not just pilot assets. Include old templates, poor-quality scans, and known exceptions. If one vendor causes constant issues, create a focused sample set for that format.
Don’t wait for some giant overhaul, either. Smaller retraining cycles are usually easier to manage than one massive refresh after months of drift.
3. Tighten intake and document preparation
If people are uploading unreadable images, you have an intake problem. Add file quality checks. Standardize scan settings where you can. Split multi-document packets before extraction if your process allows it. Even a small improvement here can lift overall results pretty fast.
4. Strengthen classification before extraction
If multiple document types come through the same channel, classification needs real attention. You may need better document splitting, a more explicit classifier, or separate intake paths for certain business processes.
Because once the wrong model touches the wrong file, everything after that gets noisier.
5. Add confidence-based human review
Not every file should go straight through. That’s fine.
Set confidence thresholds by field importance, not just one blanket number for the whole document. Invoice total, due date, and supplier name deserve stricter review than less critical metadata. That keeps your team focused where mistakes actually matter.
6. Fix downstream validation and mapping
Review where extracted values land. Maybe supplier names need normalization. Maybe date formats need transformation. Maybe line-item logic belongs in a separate review step rather than the first-pass extraction.
A lot of production “accuracy” work is really data engineering and workflow design—dressed up in business clothing.
7. Treat the model like a managed asset
Give it an owner. Track version changes. Document what sample sets were used. Note when a vendor template changed or a business unit introduced a new form. If nobody owns the model after go-live, drift is a lot more likely to slip by unnoticed.
The practical standard to aim for
You probably don’t need perfection. Most organizations don’t.
What you need is a process that reliably handles the bulk of documents, surfaces uncertain cases quickly, and gets better over time without heroic effort. That’s a far better target than expecting the model to work like a human clerk on every oddball file from day one.
And here’s the bigger point: a production-ready document automation solution is not just a trained model. It’s the combination of document intake, classification, extraction, validation, exception handling, and operational ownership. When one of those pieces is weak, “accuracy” is usually where the pain shows up first.
If your results fell after go-live, don’t assume the AI failed. More often than not, production just showed you what your real document process looks like.
Your next step is simple: pull 25 recent failures, sort them by cause, and see which bucket is really driving the problem. You’ll know pretty quickly whether you need retraining, better routing, cleaner inputs, or a stronger review workflow. Once you know that, the fix usually gets a whole lot more straightforward.


